Aaron Wood

Aaron Wood
  • AI Platform Engineer
  • Greater Toronto Area, or remote

I build the platforms other engineers build on. Right now that is an AI platform. Before it, a payments layer other engineers are still extending.

What I do

Seven years inside one enterprise platform, and two platforms built from nothing

Most of my work is infrastructure with an internal user base: the layer a product team injects and stops thinking about. I like the part where nothing exists yet and the shape of the thing is still an argument. I also spend a lot of time in rooms with executives, product managers and customers, which is why I care whether the abstraction survives contact with a real business. Review is half of it: in the past year I approved 284 of other engineers' changes while merging 315 of my own, and on our cross-platform client codebase I approve more than I write. I have also built a multi-agent prototype in Python, orchestration on Google's ADK: a coordinator that decomposes a request and delegates to specialist sub-agents, plus agents wired to MCP tool servers. Before that, nine years at a national media company, building their platforms end to end rather than managing from a distance.

Not all of my work is code. Some of it is the culture engineers work in. I have hosted the company's quarterly hack days for four years, taken over from our VP of Engineering: I run the demo session, announce each project, hold presenters to three minutes and say something useful about what they built. I sit on the committee that plans the learning programme around it, a weekly tech-talk discussion and a book club. For the bigger demos I drive OBS from a Stream Deck so I can cut between an iOS simulator, the web app, the code and the documentation without dead air, because a demo that stalls is a demo nobody believes.

  • LLM platform architecture
  • Multi-tenant SaaS
  • Payments integration
  • Distributed systems
  • Multi-agent orchestration
  • Evaluation and guardrails
  • API design
  • PHP
  • TypeScript
  • React
  • Python
  • BigQuery
  • GCP
  • Google ADK
  • MCP

Platforms

The first card and the last are the two built from nothing. The two in between are built on the first. Architecture only: no employer code, no client names, no internal identifiers.

A provider-agnostic AI platform

In production since 2025

One gateway. Every product team's model calls run through it, and none of them name a vendor.

Problem
Model calls were going to spread across a large monolith, each with its own client, its own error handling, and no way to answer "what is this costing us, and for which tenant?"
Design
A single injectable service behind a narrow provider interface. Callers pass a model variation such as "normal" or "pro". No calling code anywhere names a vendor. Requests persist per tenant with input and output token counts, giving cost attribution and full history for free. I built and shipped that persistence layer myself, staged from development through staging to three production regions.
Result
Customer summaries, AI-generated preferences across two generations, message generation with brand-guideline enforcement, and the dashboard generator below all ship on the same foundation. Every rollout is gated per tenant. In production it carries enterprise tenants across those regions, and volume has grown substantially over the past year. Growth is nowhere near even between regions, which is why I describe the platform as a whole rather than quoting the flattering region.
Measured
The retry path is the one I have actually measured: in a representative week it roughly halved the user-visible failure rate, and no request ever exhausted its four-attempt budget. The per-request token accounting earned its place separately: it showed the busiest surface and the most expensive one were not the same: one feature carried a minority of the requests and most of the token spend, at several times the cost per call of anything else, because it ships a large context and gets a short answer back. Input dominates output by a wide margin across the platform, which puts the optimization on what gets sent rather than on what comes back.
Where the model stops
The preference engine on it is the clearest case of a call I keep making: the model extracts and classifies product attributes, but the matching itself is a weighting formula I designed, recency tiers against purchase consistency and clustering, with returns scored negatively. No model decides a preference. When that engine was rebuilt onto the warehouse for its second generation the formula was ported across unchanged, and the deterministic half was the half worth keeping.
Architecture diagram. Web, iOS and React Native clients all call the same request endpoints. Those endpoints, plus the internal API and the job queue, each inject one shared gateway. The gateway is the only code that names a vendor model: callers pass a variation such as normal or pro, and it records per-tenant token counts. It calls Gemini today, and a second vendor can be added behind the same interface without changing any caller.
Callers pass "normal" or "pro", never a model name, so a second vendor means writing one connector and changing no caller.

PHP Vertex AI Gemini response schemas token accounting feature flags job queue

An agentic dashboard generator

New in production

A short description goes in; a working dashboard comes out.

Problem
Every customer wants a slightly different view of their own data, and each one was a ticket: someone writes the warehouse SQL, someone lays out a screen, someone ships a release. That works for the first few customers and then it stops working.
Design
A generation job turns a plain-language request into a spec: warehouse queries, computed fields, and the UI components bound to them. The spec is data, not code, so the same definition can be validated, repaired, versioned, localized, and rendered on web and mobile.
Result
A dashboard that used to be a release cycle is now a generation job, with a human approving each one before it goes live. Built with a second backend engineer: I designed the generation, validation and repair pipeline, and I am the top author on the renderer.
How it is evaluated
The grading is deterministic, which is the kind I trust: every generated query is executed against the warehouse before a dashboard is shown, and the results have to be internally consistent, since a monthly total can never fall below the weekly one inside it. Nothing is graded by a model. Separately, for prompt work itself, I keep my own tooling: variants run repeatedly across model tiers, results stored and compared, and a second model used to grade the differences. Repetition is the point, because one good answer from a non-deterministic system is not evidence. A colleague later built the reusable version the team shares. Mine is the local one I iterate with, and the part worth knowing is why the input data has to be held constant or the comparison means nothing.
Pipeline diagram. A generation job turns a plain-language request into a spec. The spec passes through fourteen deterministic repair steps, each idempotent, then is validated by running its queries against the warehouse. A single failing query goes to a targeted fix and is spliced back into the spec instead of regenerating everything, which is the repair loop. When the repair budget runs out the job stops and asks a person instead of looping.
The dashed path is the repair loop. The dotted one is where the job stops and asks a person instead of looping, which is the line that mattered most.

PHP BigQuery Gemini spec-driven UI job queue React Native renderer server-sent events

A message system that learns your voice

In production since 2025

Drafts that start closer to how you actually write, and get closer over time.

Problem
A generated customer message is only useful if it sounds like the person sending it. A draft that reads like nobody gets rewritten from scratch, which is slower than not having it. On top of that, every brand has rules about tone, banned words, signatures and whether emoji are allowed, and those rules differ by channel.
Design
Prompt assembly is layered and ordered: who the message is for, then the sender, then the location, then the brand rules, then the channel. Above that sit personas at three levels of specificity, with the most specific winning, and each one is keyed per channel rather than per person: the same employee writing a text and writing an email are two different voices, and collapsing them into one flattens both. Every layer is separately gated, so any of it can be switched off for one tenant without disturbing the rest.
Result
Drafts that land closer to the sender's own voice, with brand rules enforced per channel underneath. It runs continuously across eighteen distinct request types, and the eighteen are not ad hoc: three subjects (the employee, the customer, and the relationship between them) times three operations (generate, refresh, evolve from a comparison) times two channels. The whole matrix is exercised in production. Mine since the first version, and still mine: I have maintained and extended it through every generation it has had.
Flow diagram. Three persona levels, employee, customer, and their relationship, resolve most-specific-first into layered prompt assembly, which produces a draft. A person then edits and sends the message. That sent version is diffed against what was generated, asynchronously and off the send path, and the persona evolves from the difference. The analysis is constrained to a shared style glossary with fixed value ranges so the vocabulary cannot drift.
The loop only works because the vocabulary is pinned: a free-form analysis would drift until the personas stopped meaning anything.

PHP Gemini prompt layering job queue feature flags per-channel rules

A multi-provider payments layer

In production since 2022

Card-present terminals, gift cards, and online, behind one interface.

Problem
Multiple payment providers, physical terminals in retail stores, and real money in luxury retail, where a single basket can be worth thousands. When a terminal fails, the brand loses money and there is someone waiting at the counter.
Design
A provider-abstraction layer with connectors for each processor, per-tenant transaction logging, metrics, and provider health checks, so adding a processor extends the transaction flow rather than changing it.
What it taught me
An outage. A missing index made payments time out under load, and a handful of charges went through at the provider with no record of them on our side. The index was a real problem and we fixed it, but the timeouts exposed a second one: nothing durable was written before we called the provider, so an unknown outcome had nothing on our side to reconcile against. I built the attempt record: a row written before the call, with its own status lifecycle, its own table and its own indexes, so a charge cannot happen without something left behind to recover from. It is what the pending-attempt check below is looking at.
How it is watched
I designed the alerting framework that sits over it: scheduled reconciliation checks behind check and publisher interfaces, so a check knows nothing about where its alert goes and a publisher knows nothing about what raised it. The checks look for the things that should never happen, an orphaned transaction, an attempt stuck pending, an order with no customer token, a processor error code breaching its threshold. Seven other engineers have added checks and publishers to it since, without changing the interfaces, which is the same outcome as the connector seam and the reason I think the pattern is the point rather than either system.
Result
Still in production years later, and the count is the proof the seam held: I wrote the interface and seven of its connectors, and eight more have since been added by other engineers. It stopped needing me, which is the outcome you want from an abstraction. It is still the transaction path, running across multiple currencies and multiple providers, including card-present terminals in stores.

PHP card-present terminals gift cards distributed locking idempotency metrics

Developer tooling

Nobody asked for this. I built it because the same twenty minutes kept disappearing at the start and end of every ticket.

Twelve tools, from ticket to published documentation

In daily use

Each one removes a specific twenty minutes I was spending by hand. They present options; a person decides, and nothing publishes without an approval.

What it does
Takes a ticket from untouched to merged and documented: open it with the right branch, worktree and context already loaded; review the merge request; write and publish its description; triage reviewer comments into a work plan; keep track of what is in flight across projects. The effect on my own output is the one measurement I did not expect to be this clean: across two years of merge requests, every month after this landed produced more merged changes than any month before it, with a clear gap and nothing in between the two groups. Correlation, not proof, and merge requests count shipped increments, not effort.
Documentation
The documentation tool does not just write prose. It generates the diagrams and it drives the product to capture its own screenshots, on the web app and on the iOS app, walking the real interaction and embedding the result. The merge-request descriptions use the same capture path, so a reviewer sees the change rather than a paragraph claiming it happened.
Beyond me
Pieces of it have been packaged up and handed to other developers on the team.

Claude Code Python Playwright iOS simulator capture Jira REST GitLab API Confluence API

Darkwatch

The pipeline and the product were built together, and each influenced the other’s direction.

A real-time session manager for a tabletop role-playing game, built solo. I did not build a toolchain and then look for something to point it at: the nineteen skills and the application grew together, and that is the part worth saying. Every gap in the tooling showed up as friction on a real ticket, and every fix had to survive the next one. A separate toolchain from the twelve tools above, built on my own time. Five months, 1,014 pull requests and 1,338 commits, driven by 1,684 tracked issues of which 1,387 are closed, rather than one impressive afternoon.

Nineteen skills that plan, implement, review and ship

In daily use, on a live codebase

Agents fan out across tickets in parallel git worktrees. Every gate that could merge something is deterministic, and every write to a shared system stops for a person.

Who decides
Every gate that can let code through is deterministic, never a model's opinion: typecheck, lint, import-cycle and dead-code checks, 168 Playwright specs sharded in parallel, visual regression, performance budgets, supply-chain audit. The agent writes the code and opens the pull request. It gets no say in whether that code is good enough to merge. Anything that writes to a shared system stops at a person first. And nothing closes on a claim: a resolved ticket moves to a QA state and closes only once a written test plan has been run against the running application.
Measuring it
A reopen check flags any issue closed and then reopened inside seven days, on the theory that a reopened issue means the first fix missed something. Building it taught me more than running it did. A later audit found fourteen fixes that had stopped one case short of the rest, and the check had caught none of them: when we find one, the convention here is to file a fresh issue rather than reopen the closed one. So the number stays green whether the fixes were good or not.
The app underneath
Real-time state synchronization across a table of players, live maps with fog of war, character and combat management, an image pipeline and a component library. React and TypeScript on Node and MySQL, 18 CI workflows, nightly deploys to self-hosted infrastructure.
Pipeline diagram. A ticket becomes a plan, and the plan halts for my review before any code is written. Approved work fans out to several agents, each in its own isolated git worktree, so they run in parallel with no shared state. Each agent's diff is then read by a second agent whose only job is review. After that it reaches the deterministic gates: typecheck, lint, import-cycle and dead-code checks, sharded Playwright specs, visual regression, performance budgets and a supply-chain audit, which are tests rather than opinions. Past the gates, a QA pass runs the written test plan against the running application, and the ticket closes on that verified pass, not on a claim that the work is done. A red gate loops back to the agent that produced the work, not to me.
The worktree isolation is what makes the fan-out safe: concurrent agents never share a checkout, so one run cannot corrupt another.

React TypeScript Node MySQL Playwright self-hosted CI agent orchestration

Every still and clip below was captured by the documentation and QA tooling, planned and executed by the tooling to showcase a feature or to validate a specific acceptance criterion.

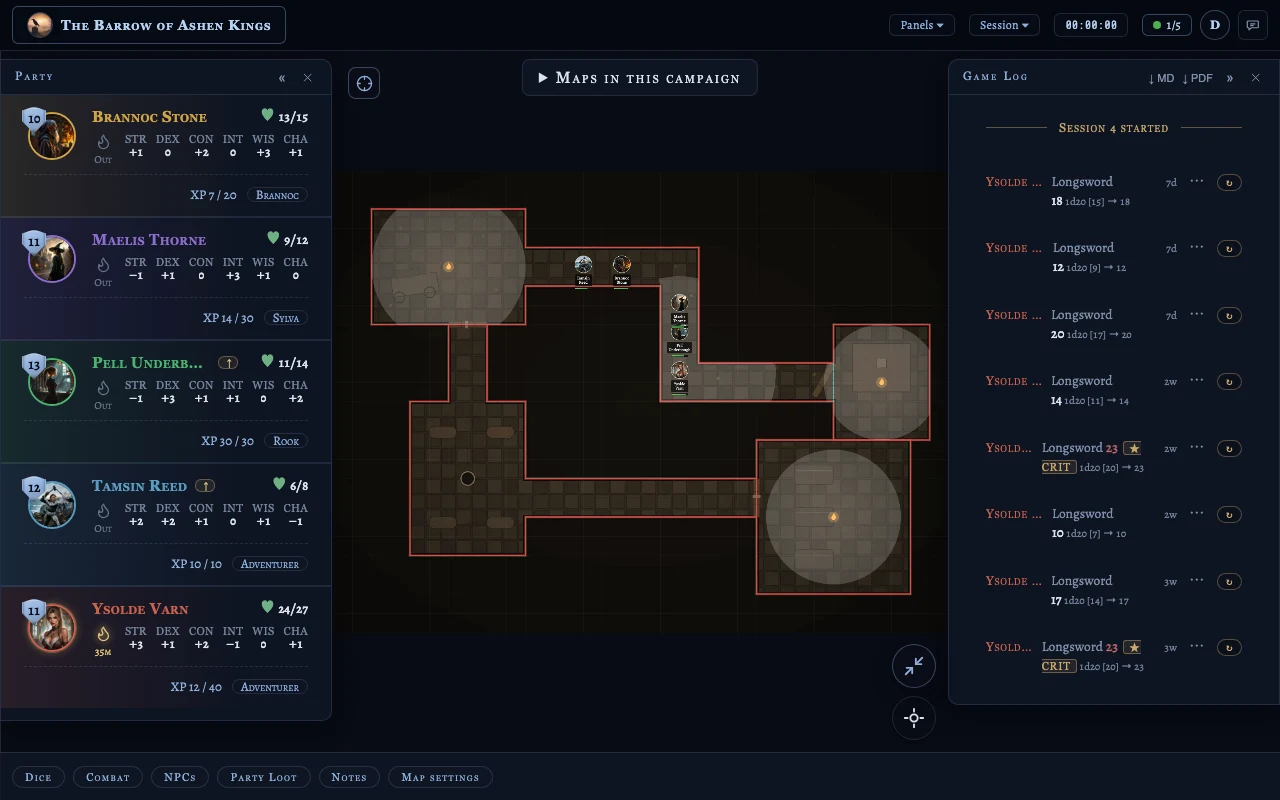
The DM's War Table during a live session. The party roster runs down the left with each character's hit points, ability scores and experience. The centre is a shared battle map, lit rooms and corridors picked out against unexplored black, with player tokens and red wall segments. The game log on the right lists each roll as it is made. Tabs along the bottom reach dice, combat, NPCs, party loot, notes and map settings.
The DM's War Table. One screen that has to stay correct while several players act at once.
Panels, rearranged live. The DM moves panels while the session is running. Every player's view stays in sync.
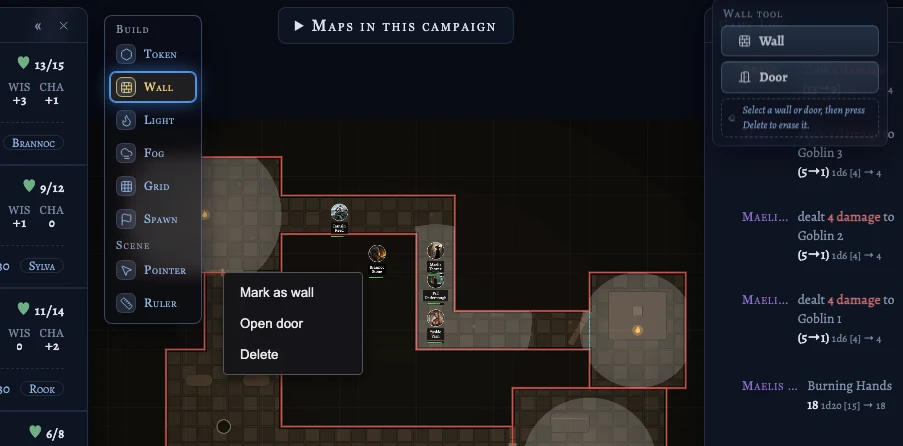
The DM's map building tools. A left rail offers token, wall, light, fog, grid and spawn tools plus a pointer and ruler. Wall segments are drawn in red straight onto the map, and a context menu on a selected segment offers mark as wall, open door, or delete. The combat log on the right keeps resolving damage rolls while the map is being edited.
Authoring the walls. Those red segments are what line of sight is computed against. Open a door and the sight lines change with it.
Line of sight. Walls and doors occlude in real time as a token moves. The hardest thing in the app.
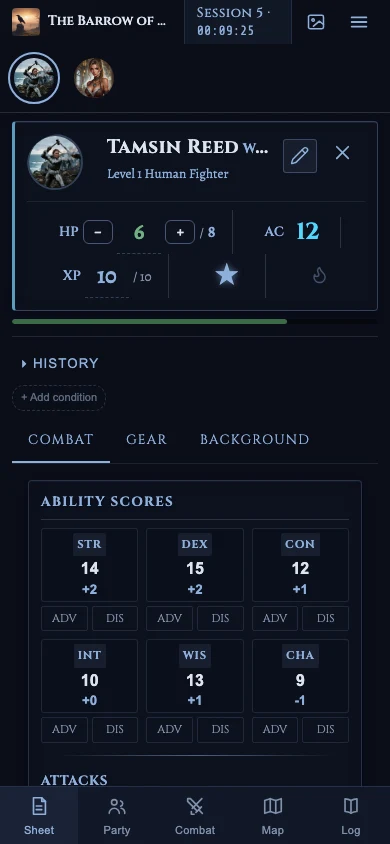
The same live session on a phone at 390 pixels wide. A character sheet fills the screen: hit points, armour class and experience across the top, then ability scores and attacks below, with tabs for combat, gear and background. A bottom bar switches between sheet, party, combat, map and log. It is a single-column layout designed for the phone rather than a shrunken desktop view.
The same session on a phone. Players are at a table with phones, not laptops, so this is the real surface rather than a fallback.

Open source

The toolchain I actually ran

Public, MIT

Darkwatch-specific and further along than the general version. Not really a drop-in tool: more a showcase of what got built, and what it took to find the line between what an agent can be trusted with and what it cannot.

What is in it
Nineteen skills, eighteen CI workflows and a hundred and twenty scripts, taking a piece of work from someone mentioning a bug to shipped and verified. Built across 109 working days. 184 files of tooling, 41 of them unit tests sitting beside the thing they test.
Why it is public
It is wired to one project's tracker, database and CI, so it will not drop into your repository. The record matters as much as the code though: it shows the reasoning, and what I learned building it.
Repository
github.com/SilicaGel/darkwatch-toolchain

JavaScript Shell TypeScript MIT Claude Code CI gates

FlightDirector

Open, in progress

The general version. Same ideas, built from the start to drop into anyone's repository rather than mine.

What it is
Skills and plugins for AI harnesses such as Claude Code and Codex, built with my brother. Much of the Darkwatch toolchain is being ported into it, with the project-specific wiring taken out and the design kept.
Where it ends up
The intent is for FlightDirector to run Darkwatch, so the general version replaces the one it came from.
Repository
github.com/AICrafting/FlightDirector · flightdirector.build

Shell Python MIT Claude Code Codex

Contact

What I am looking for next

I am looking for a staff-level engineering role on a platform or applied-AI team, early enough that the hard calls are still open, and a real production load to test them against. Remote, or Greater Toronto Area.